An AlphaZero-inspired reinforcement learning chess engine built from scratch. Uses a Transformer neural network as the evaluation backbone, Monte Carlo Tree Search (MCTS) for move selection, and a deterministic Alpha-Beta endgame solver that takes over in simplified positions to force checkmate.
📂 GitHub Repository: RLChess
Sample Game
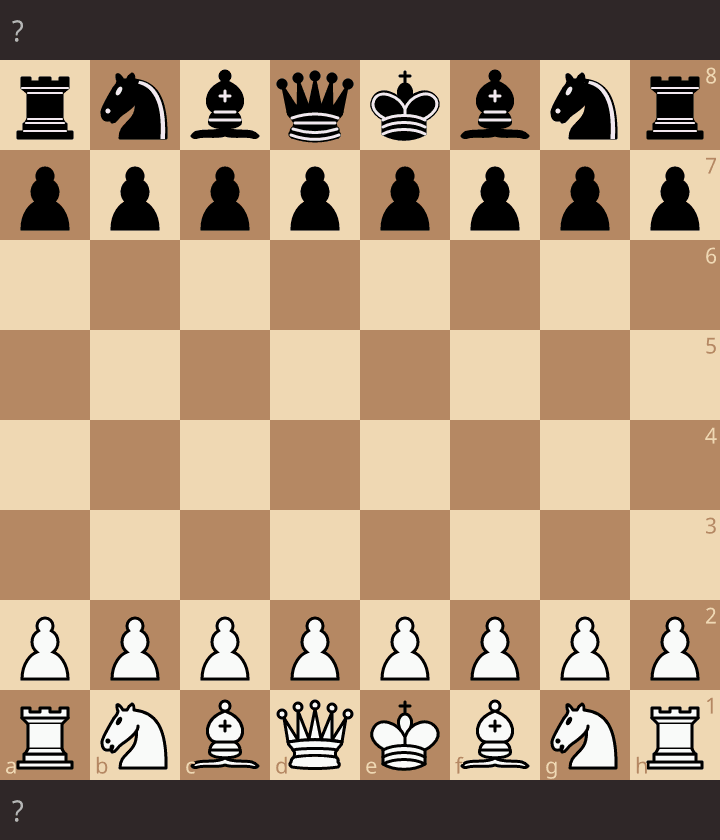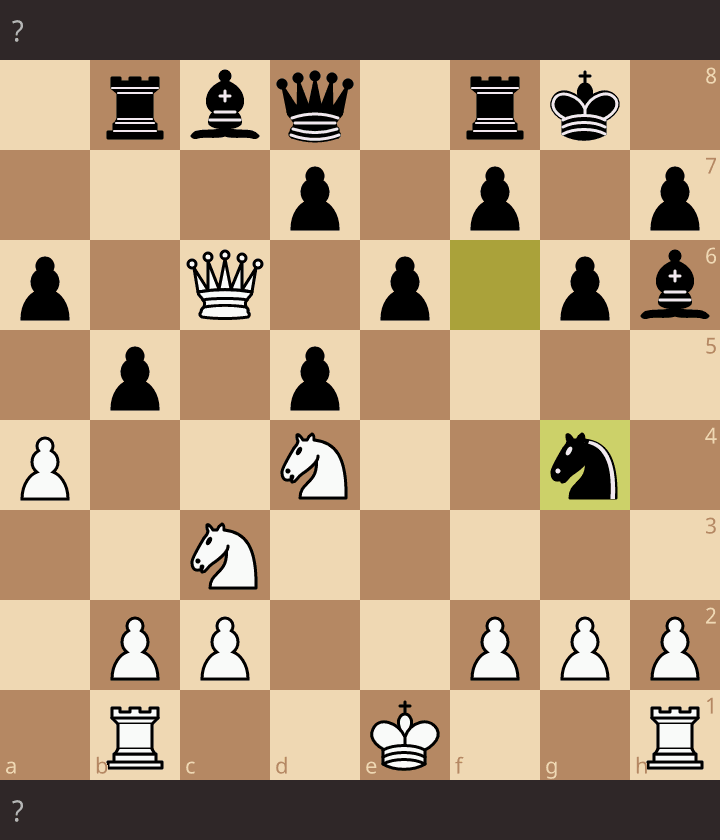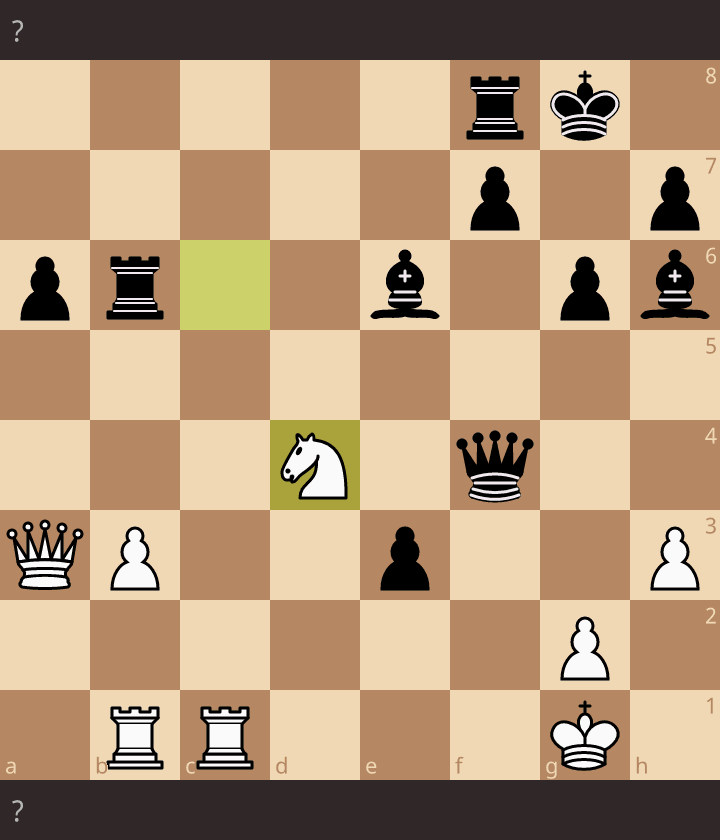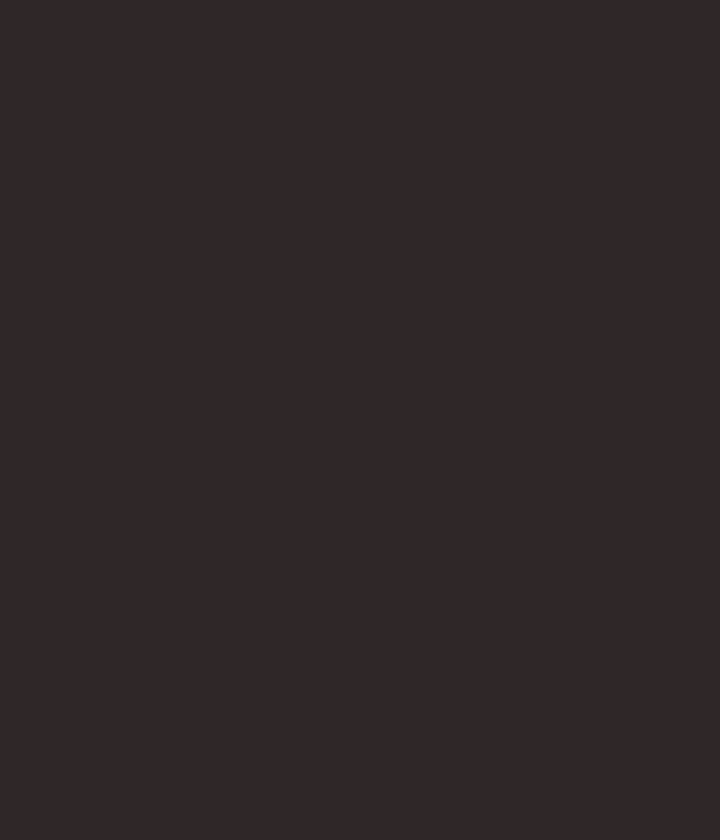
White - 300000 episodes
Black - 700000 episodes
Architecture
┌─────────────────────────────────────────────────────┐
│                    Board State                      │
│                  (42 × 8 × 8 tensor)                │
│  turn + pieces + attacks + castling + en passant    │
│                  + 8-move history                   │
└───────────────────────┬─────────────────────────────┘
                        │
                        ▼
┌─────────────────────────────────────────────────────┐
│              1×1 Conv Projection (42 → 512)         │
│           + Learnable Positional Encoding           │
│                  (64 square tokens)                 │
└───────────────────────┬─────────────────────────────┘
                        │
                        ▼
┌─────────────────────────────────────────────────────┐
│            Transformer Encoder (×10 layers)         │
│         d_model=512, 8 heads, FFN=2048              │
│              Pre-Norm, batch_first                  │
└──────────┬────────────────────────────┬─────────────┘
           │                            │
           ▼                            ▼
┌──────────────────────┐  ┌──────────────────────────┐
│     Policy Head      │  │       Value Head         │
│  Linear(32768→4096)  │  │   Linear(32768→512)      │
│  Linear(4096→4672)   │  │   Linear(512→1)          │
│   → raw logits       │  │   → tanh ∈ [-1, 1]       │
└──────────────────────┘  └──────────────────────────┘
- Policy Head: Outputs logits over 4672 possible actions (4096 normal moves + queen promotions, 144 underpromotion slots for Knight/Bishop/Rook)
- Value Head: Outputs a single scalar predicting the game outcome from the current player’s perspective
- ~30M parameters — designed for an RTX 3080
MCTS (Opening + Middlegame)
Standard AlphaZero-style MCTS with PUCT selection, Dirichlet noise at root for exploration, and 400 simulations per move. The neural network provides both the prior probabilities for edge selection and the leaf evaluation.
Alpha-Beta Solver (Endgame)
When ≤ 7 pieces remain on the board, the engine automatically switches from MCTS to a deterministic alpha-beta search with iterative deepening (up to depth 20). This solver uses MVV-LVA move ordering, king-cornering heuristics, and passed-pawn proximity bonuses to force checkmate reliably.